| Custom-trained model | Correction-based TIO | |
|---|---|---|
| Problem it solves | Cost per call at scale | Hours lost to keying |
| Suits | Very high daily volume | Lean desks |
| How it learns | Baked in at training | Each fix becomes a rule |
| A new customer appears | Waits for retraining | Applies on the next email |
A custom AI model is a language model fine-tuned on one company’s own operational data, dedicated to that company, and not shared with other customers. The economics only work above a volume threshold: a training pipeline pays for itself by cutting the cost of a model call that repeats thousands of times a day, so the savings scale with transaction count. That is a real solution to a real enterprise problem. It is not the problem most freight forwarders and warehouse operators have. An independent forwarder running 25 lots and 20 customs filings a week is not losing money on inference cost. They are losing roughly two days a week to a person reading a booking confirmation and typing what it already said into the TMS. Those are different constraints with different fixes, and the second one does not require a training run to solve.
What is a custom AI model in supply chain software?
A custom AI model is a smaller model trained on the workflows already running through one customer’s account, then dedicated to that customer alone. It differs from a general-purpose model in where the business context lives.
A general-purpose model was trained on public data. It knows how language works and how a bill of lading is usually structured, but it knows nothing about your specific consignees, your preferred carriers, or how your team handles a short-shipped container. None of that was in its training data, so every time it runs, someone has to hand it that context again: the customer list, the routing rules, the current exception.
A custom model moves that context inside the model itself. Correct it once on a preferred carrier and it carries the pattern forward without being reminded. The vendor can also deploy it on infrastructure the customer controls, rather than routing every request through a third party. That solves two genuine problems at scale: the cost of running a general-purpose model against a large volume of transactions, and the exposure of handing a vendor a growing record of proprietary operating knowledge.
When does a custom AI model actually pay off?
Training a model takes months of engineering work, and it pays off in proportion to how many times the finished model runs.
The sequence is fixed. Deploy the system into production. Accumulate enough real workflow data to form a training set. Clean, structure, and anonymize it. Benchmark candidate architectures on accuracy, latency, throughput, and infrastructure cost. Fine-tune, evaluate, optimize inference, deploy. Each step is real engineering work, and none of it produces value until the last one lands.
That math works when a model call repeats thousands of times a day, because a small per-call saving multiplied by an enormous call count is a large number. Invert it and the logic collapses. At a few hundred calls a week, the same per-call saving multiplied by a small call count is a rounding error, and it still costs a full training pipeline to capture.
How much volume does a lean forwarder or warehouse operator actually run?
Tens to a few hundred jobs a week, nowhere near thousands of transactions a day. A US import freight forwarder running TIO in production handles 25+ lots and 20 ISF filings in a typical week.
The hours going missing in that operation are not in inference cost. They are in transcription. Lot creation ran about 30 minutes per job by hand. ISF filing ran about 15 minutes per filing. Across 25+ jobs and 20 filings a week, that is roughly two days of a person’s week spent reading documents and typing their contents into fields.
A warehouse keying delivery orders has the same shape of problem in different paperwork. A DO arrives by email, someone reads it, and someone types the shipping entry into the system by hand. The document is different from a forwarder’s bill of lading; the work is the same work, and it scales with headcount rather than with model calls.
The wider pattern matches. A single ocean import job generates 30 to 60 emails across its lifecycle, and at 100 jobs a month that is 3,000 to 6,000 emails on ocean import alone. At 40 to 80 ISF filings per month, the manual filing chain alone consumes 13 to 40 hours of ops time. The bottleneck is not that any one email is hard. It is that there are thousands of them, each in a slightly different format, and a person reads every one from scratch.
That is an operator-hours problem. A fine-tuned model that gets cheaper per call at massive scale does not touch it.
Custom model or correction-based automation: which fits your operation?
The two approaches solve different constraints:
| Custom fine-tuned model | Correction-based TIO | |
|---|---|---|
| Constraint it solves | Per-call inference cost at high volume | Operator hours lost to manual entry |
| Fits an operation running | Thousands of transactions a day | Tens to a few hundred jobs a week |
| Time to first value | After the training cycle completes | A scoped pilot |
| Prerequisite | Production data set, cleaning, benchmarking, infrastructure | A mail rule, sample documents, access to your TMS and an adapter for it |
| How it learns your business | Patterns baked in at training time | Every correction becomes a rule immediately |
| When a new consignee appears | Waits for the next training cycle | Applies on the next email |
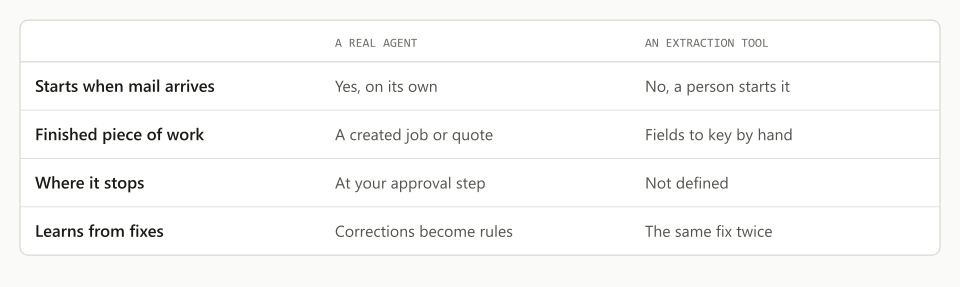
| Who approves the output | Depends on the deployment | A person files every customs filing. Each other action runs on its own, goes for review, or waits for a reply |
Neither column is wrong. The left column is the right answer for an operation whose costs scale with model calls, and the right column is the right answer for an operation whose costs scale with headcount.
How does TIO learn your business without a training run?
Through correction. The loop runs in five steps, and it starts on day one:
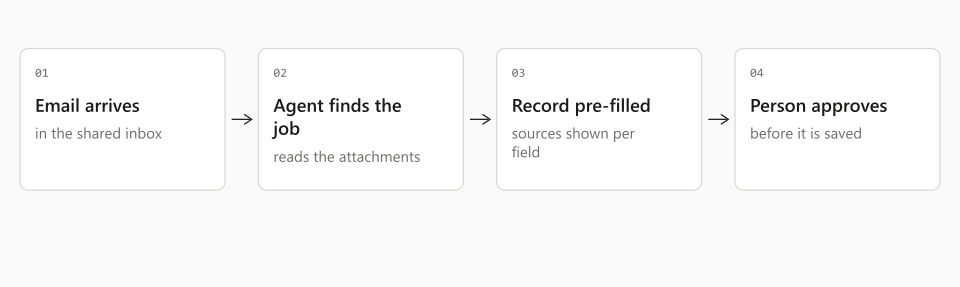
- TIO reads the document. A booking confirmation, a bill of lading, or a 10+2 worksheet lands in the inbox your team already uses. TIO reads it in whatever shape it arrived, including scanned PDFs.
- It drafts the record. It resolves the parties, pulls the fields, and carries the work to a finished draft: the ISF filing, or the lot in your TMS with charge lines.
- Your team reviews it. Where the action is set for review, a person checks the record against the source document. A customs filing is always a draft that a person files.
- A correction becomes a rule. When someone fixes a party name or a classification, TIO keeps it. Your consignee list, your carrier preferences, your HTS history, the way your team writes a house bill number.
- The rule applies on the next email. The following document that hits the same pattern gets it right, without waiting for a training cycle to come around.
The practical difference is timing. A custom model improves when a training run finishes. Correction-based automation improves on the next message. For the operation above, where lot creation went from about 30 minutes to seconds, no training run stood between the first job and the gain.
What should you ask before buying either one?
Ask which constraint your operation is up against.
If your costs scale with the number of model calls, because you are running thousands of transactions a day, then a dedicated model with a data science function behind it is a defensible way to cut a cost that repeats at enormous volume. That is real engineering, and it deserves to be evaluated on its own terms.
If your costs scale with headcount, because the next hire is a direct consequence of data-entry throughput, then the cost of an AI call is not your problem. The 30 minutes per lot and 15 minutes per filing are your problem. A training pipeline solves a cost problem you may not have yet, and it solves it after a project, while the transcription hours keep accruing every week in the meantime.
Most independent and mid-size forwarders and warehouse operators sit in the second group, where the fix is software that starts reading the inbox correctly this week.
How does TIO handle this?
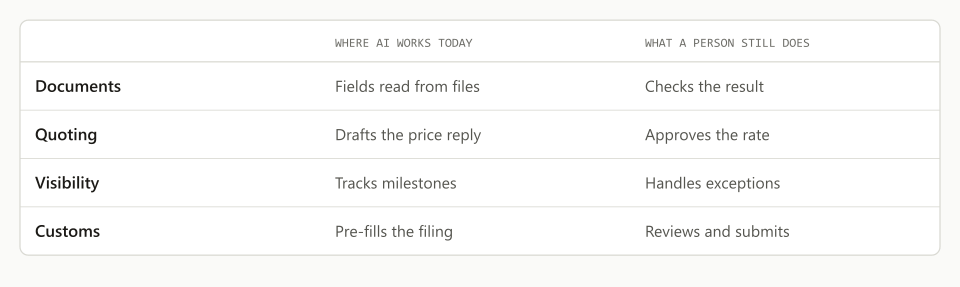
TIO runs on production-grade models and gets customized to your operation through the correction loop above, not through a training pipeline. See what TIO does. For customs preparation, TIO drafts the filing. For order entry, TIO reads a bill of lading, house bill, or delivery order and creates the lot or DO in your TMS, charge lines included, and sends a review email that shows every field. A party it cannot match, or two documents that disagree, go to a person. TIO works on top of the TMS you already run and does not replace it. Your system stays the system of record.
TIO prepares the filing as a draft. A person on your team reviews and files it. The ISF 10+2 data set is due to CBP at least 24 hours before the vessel loads at the foreign port of lading under 19 CFR Part 149. TIO files no customs entry or security filing. Each action TIO can take has its own setting: it runs on its own, it sends the work for review, or it waits for a person’s reply. Anything outside your rules goes to a person.
For what a lean forwarder’s AI problem looks like day to day, see what small forwarders need from AI. For the step-by-step of what an AI agent does inside an ops workflow, see What Is an AI Agent in Freight Operations?. If you want to see how this fits your operation, let’s have a quick discussion about your process. We work around your people and your schedule. Your people, your processes, not the other way around.
TIO builds AI systems that run logistics for freight forwarders and freight brokerages. TIO triages every inbound item and does the task inside the systems your team already runs: the TMS, spreadsheets, shared drives, a CRM and email. See what TIO does.
Frequently asked questions
What is a custom AI model in supply chain software?
A custom AI model is a language model fine-tuned on one company's own operational data, dedicated to that company, and not shared with other customers. Instead of sending every request to a general-purpose model with the business context attached, the vendor trains a smaller model on the patterns already running through that customer's workflows, then routes production traffic to it. The economics depend on volume, because the savings come from cutting the cost of a model call that repeats thousands of times a day. That fits an operation running thousands of transactions daily, not a forwarder running 25 lots a week.
Do I need a custom-trained AI model for my freight forwarding operation?
Only if your bottleneck is per-call inference cost at thousands of transactions a day, which is an enterprise-scale problem. A forwarder running 25 lots and 20 customs filings a week is not losing money on inference cost. They are losing roughly two days a week to manual data entry, and that is an operator-hours problem a training pipeline does not solve.
How does TIO get customized to my business without training a model?
Every correction your team makes becomes a rule TIO keeps: your parties, your consignees, your HTS history, your conventions. That rule applies on the very next email rather than after a future training cycle. There is no dataset to assemble, no benchmarking pass, and no infrastructure to stand up first. For one US import forwarder, lot creation dropped from about 30 minutes to seconds across 25+ jobs a week, with no training run in between.
Is a fine-tuned model more accurate than a general-purpose model for freight documents?
It can be at the scale where it makes economic sense to build one, and that is a defensible engineering tradeoff for an operation running thousands of transactions a day. For a lean forwarder, the relevant gap is between no automation and software reading the inbox correctly. Lot creation dropping from about 30 minutes to seconds across 25+ jobs a week is the measurable change, and it takes no training run to get there.
Does TIO file my ISF or write to my TMS on its own?
TIO never files a customs entry or security filing. TIO prepares the filing as a draft. A person on your team reviews and files it. The ISF 10+2 data set is due to CBP at least 24 hours before the vessel loads. For TMS records, each action TIO can take has its own setting: it runs on its own, it sends the work for review, or it waits for a person's reply.